Hemeroteca Digital
Arxiu històric de la ciutat de Barcelona
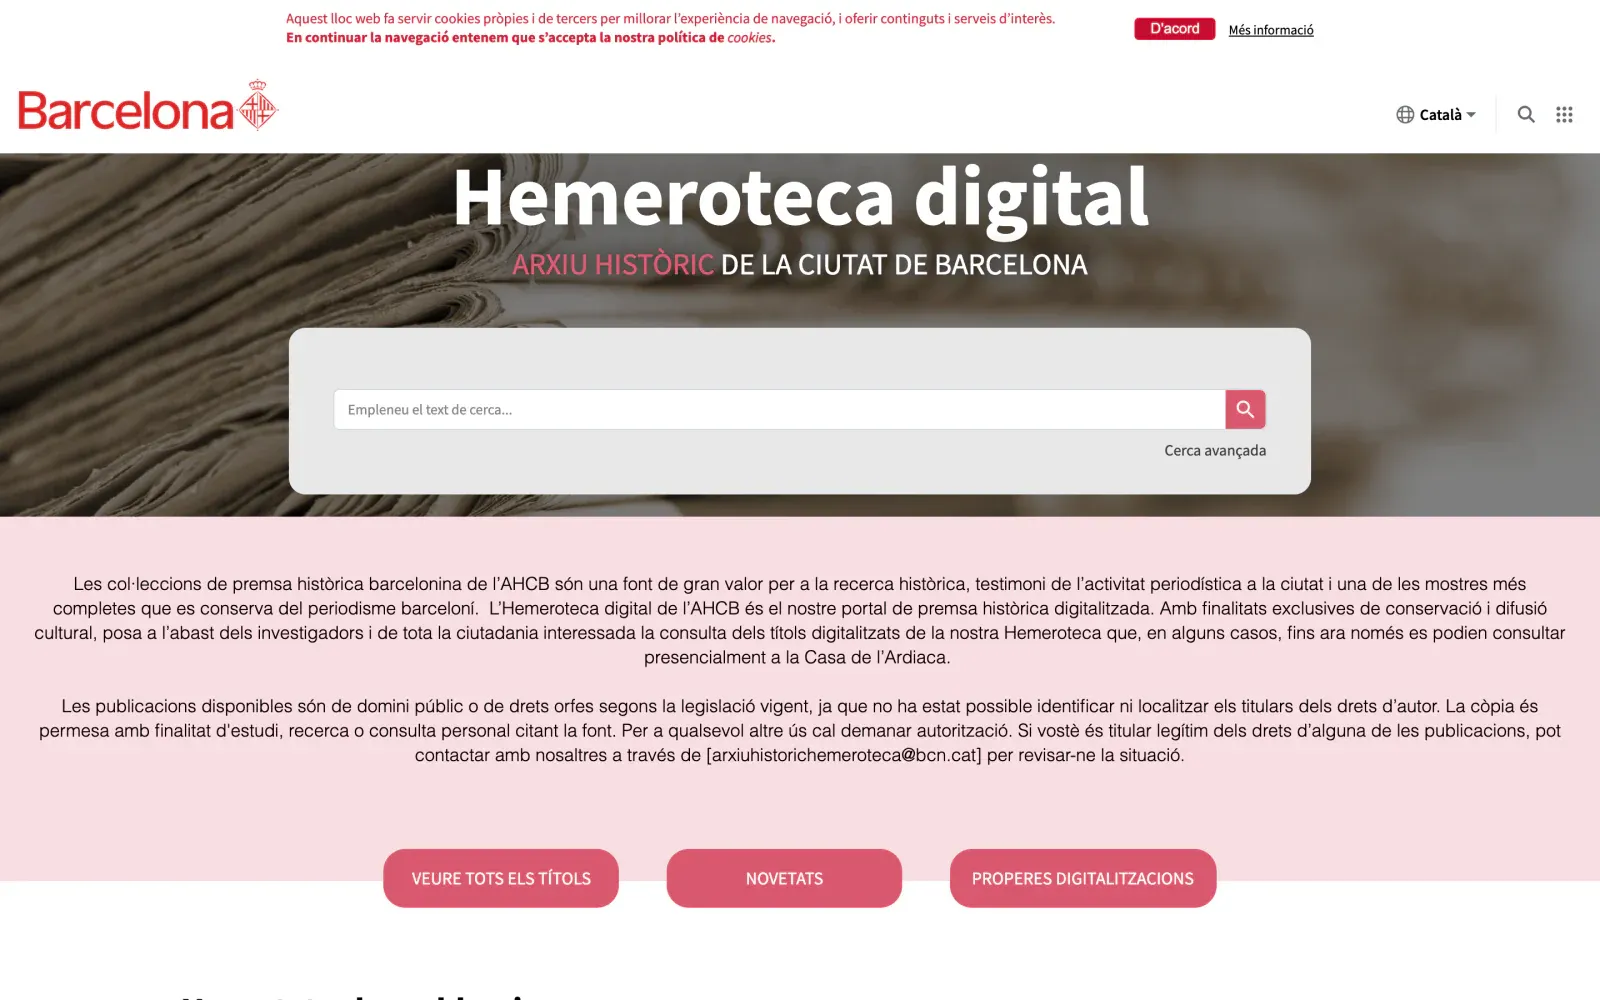
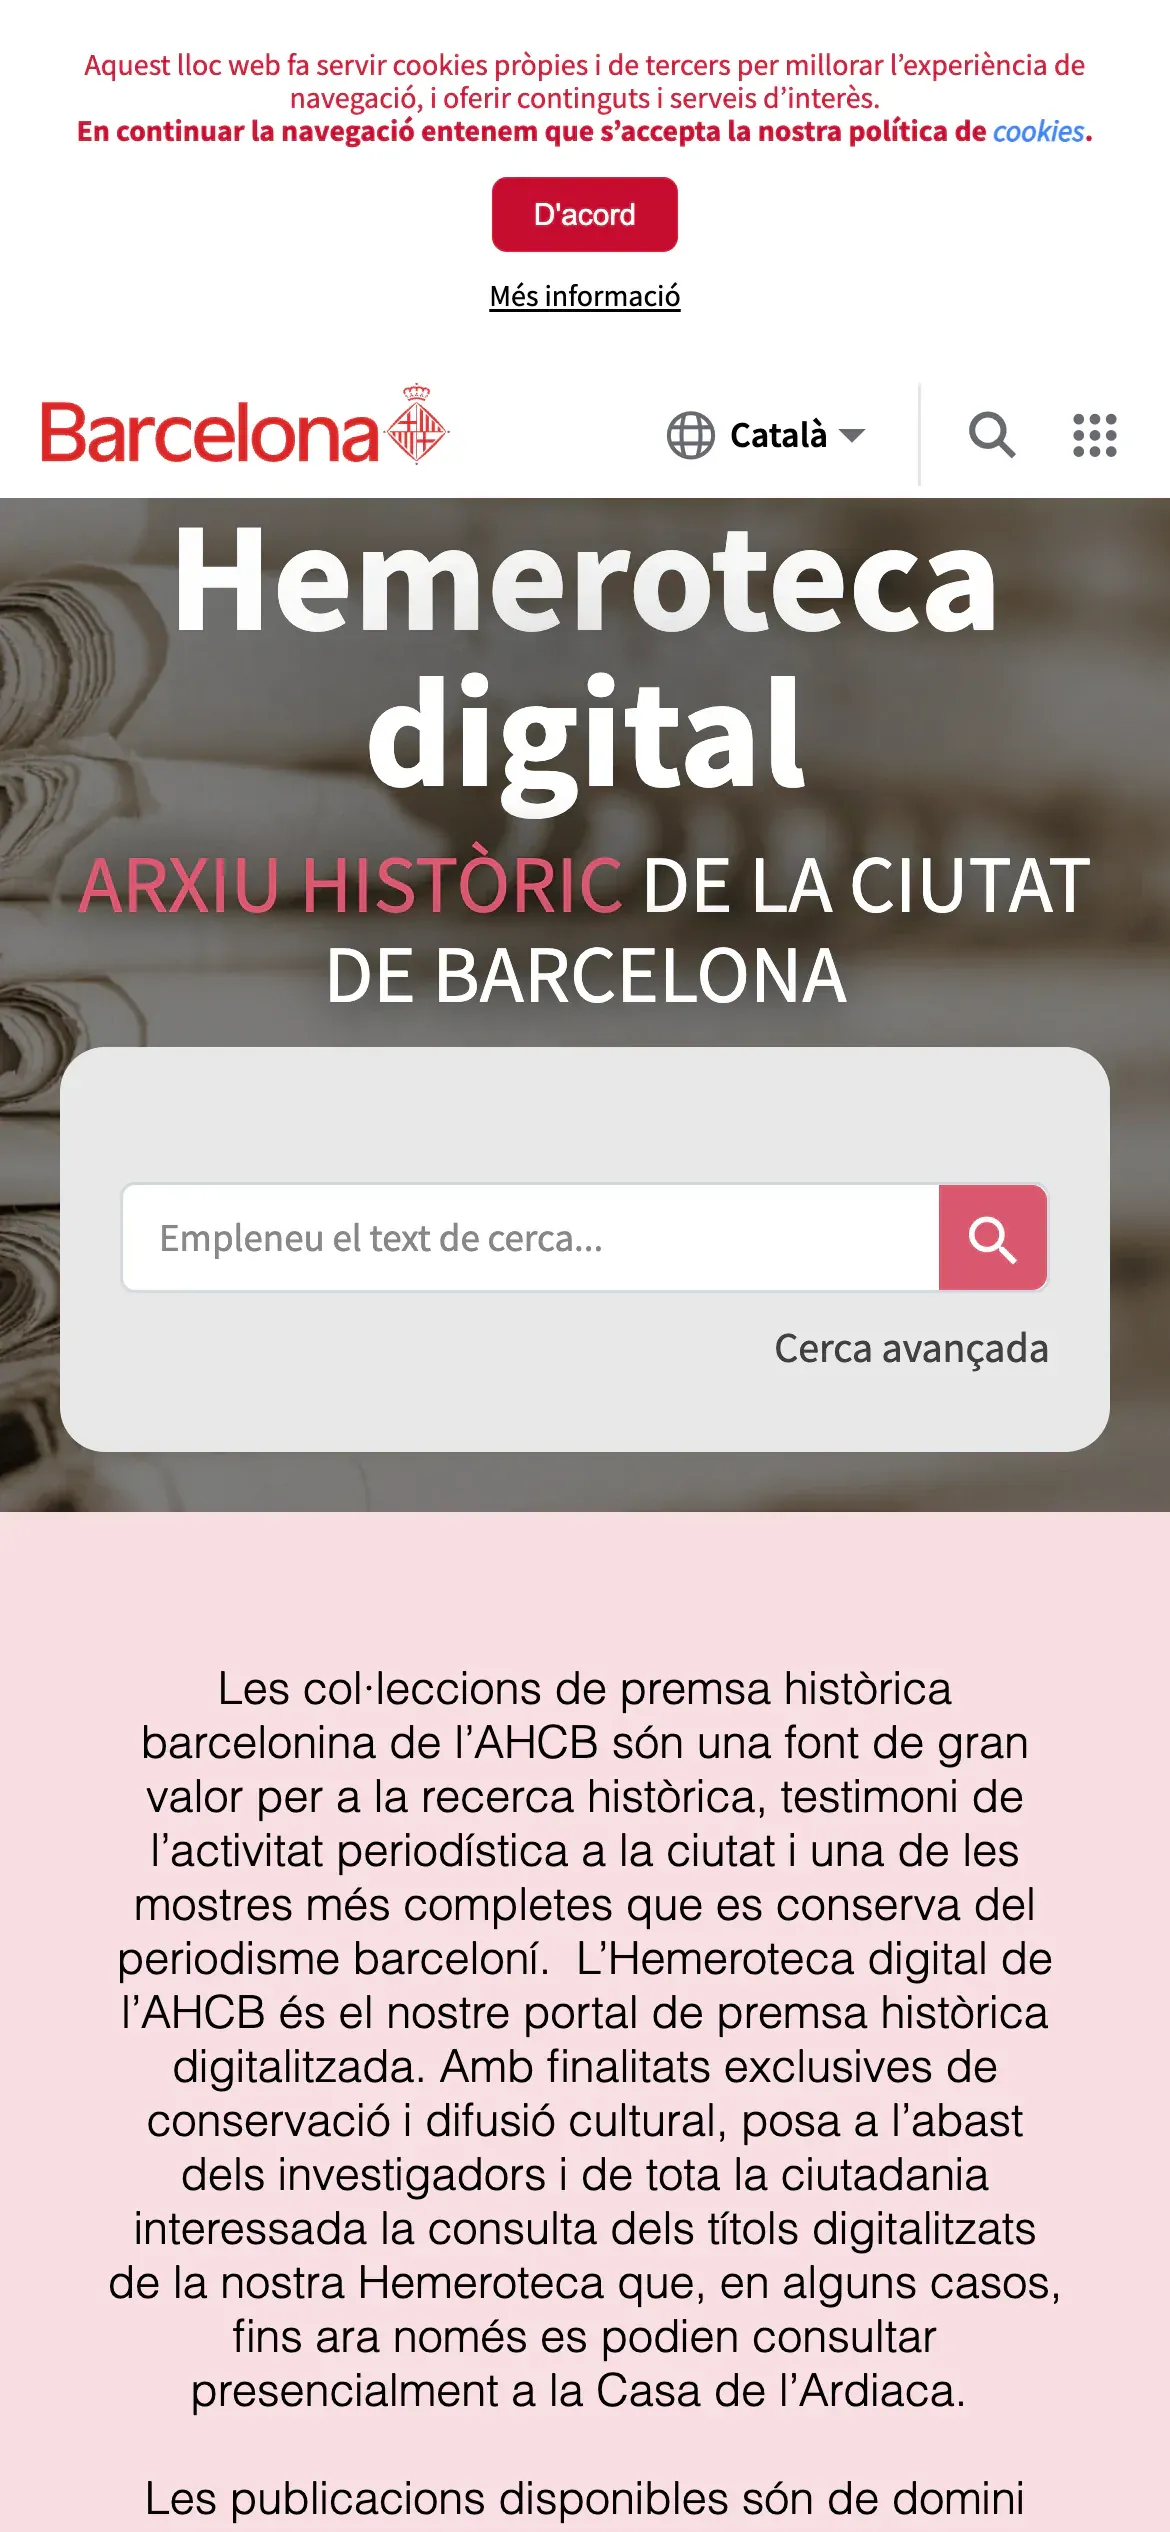
Tool for accessing the documents digitised by the Historic Archive of the City of Barcelona. It allows searching by keyword, year of publication, author, etc. Full development, design and architecture of the platform.
- Client
- Arxiu històric de la ciutat de Barcelona
- Sector
- Culture & heritage
- Year
- 2019–2023
- Duration
- 4.5 years
The challenge
The Historical Archive of the City of Barcelona holds one of the most important press collections in Catalonia: more than two centuries of digitised newspapers and magazines, from the Diario de Barcelona (1792) to the Civil War magazines and the clandestine press of the exile years.
The whole collection existed as thousands of digitised images, but with no public tool to browse it. The archive needed a platform able to index hundreds of thousands of pages and make them searchable for researchers and the public — across spellings ranging from the 17th to the 20th century.
The solution
We designed and built the whole platform: architecture, design, front end and back end, with Laravel and Vue.
At its core is a search engine built on Elasticsearch — a deliberate choice: a conventional database is not made for searching through hundreds of thousands of pages of OCR-extracted text; queries would be slow, with no notion of relevance. Elasticsearch indexes every word ahead of time, answers in milliseconds and ranks results by how well they match, however large the collection grows, without weighing down the rest of the platform.
On top of that engine we configured analysis tailored to the collection: accent- and case-insensitive search — essential for Catalan and Spanish spellings ranging from the 17th to the 20th century — and combinable filters for collection, title, author, date and language, computed by the same index on every search.
The platform connects to the Barcelona Institute of Culture's API. The archive's team launches synchronisation from the back office, either partial (only documents added or changed since the last run) or full. The server processes it in the background in batches, with progress tracking and the option to reprocess any documents that failed. New documents never have to be loaded by hand.
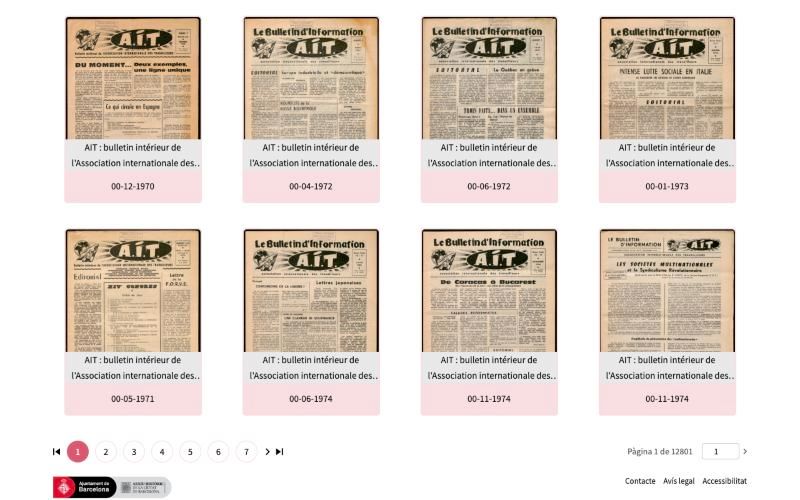
The result is two sites in one — the newspaper library and the book library — with a document viewer, PDF access, a multilingual front end and a back office for the archive's team to manage collections and titles.
Results
- +3,300
- Publication titles available to search
- 2 centuries
- Of digitised press (1792–1994)
- +1,100
- Clandestine and exile press titles
- 4.5 years
- Of continuous evolution (2019–2023)